
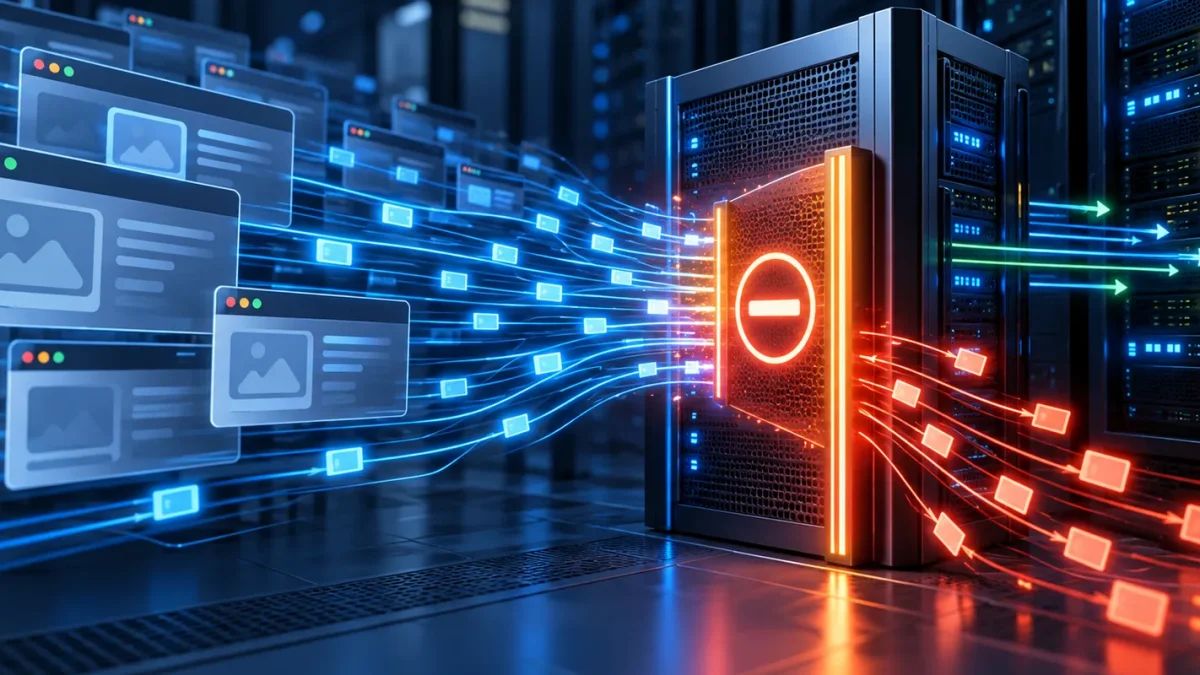
When opening a website, working with an admin panel, or using an API, you may occasionally encounter the message 429 Too Many Requests. It means that the server or an intermediate infrastructure component has restricted request processing because an established limit has been exceeded. A page may temporarily stop loading, certain website functions may stop working, and a software integration may return an error instead of the expected data.
HTTP 429 does not necessarily indicate a hardware or software malfunction or that the hosting service is unavailable. It is often the result of a protection mechanism that controls traffic intensity and prevents excessive load. However, overly strict rules or incorrectly configured applications can lead to legitimate users being blocked.
To resolve error 429, you need to identify which component returns the response, what caused the limit to be exceeded, and whether the configured restrictions correspond to the actual workload. Let’s examine the causes of this error, diagnostic methods, and practical solutions for website owners, server administrators, and developers.
What Does the 429 Too Many Requests Error Mean?
Error 429 is an HTTP status code indicating that a client has sent too many requests within a certain period. The status belongs to the 4xx class and is defined in the RFC 6585 standard.
Technical documentation may use different terms: 429 status code, 429 code, or HTTP 429. All of them refer to exceeding the permitted request rate. However, the standard does not establish a universal number of requests after which a server must return this response. Specific rules are determined by the configuration of the web server, API, proxy, CDN, or another infrastructure component.
A mechanism called rate limiting is used to control the load. It restricts the number of operations a client can perform within a specified interval. For example, a system may allow 100 requests per minute for a single account or limit the frequency of requests to a particular API method. If the client exceeds the permitted value, subsequent operations may be rejected.
Restrictions can be applied based on an IP address, account, API key, authentication token, session, or a combination of parameters. Separate rules may apply to the entire website, specific URLs, the admin panel, or resource-intensive functions.
In some cases, the server response contains the HTTP header Retry-After. It indicates how long the client should wait before trying again. The value can be provided as a number of seconds or as a specific date in HTTP format. For example, Retry-After: 60 indicates a recommendation to retry the request no earlier than 60 seconds later.
However, Retry-After is not mandatory for every 429 response. If the header is absent, the client does not receive an exact waiting time. In this case, it is advisable to gradually increase the intervals between retry attempts and follow the service documentation.
It is important to understand that too many requests does not always mean that an IP address has been completely blocked. The restriction may apply only to one API method, a particular user, or a specific type of operation. Other pages and functions may continue working normally.
Why Does Error 429 Occur?
The main reason for HTTP 429 is exceeding an established activity threshold. However, the sources of excessive requests can vary significantly. Sometimes the problem results from normal user behaviour, while in other cases it is caused by software errors, automated tools, or server settings that do not match actual operating conditions.
Limiting mechanisms can operate at several levels simultaneously. For example, a CDN controls traffic before it reaches the server, the web server applies its own rules, and an API additionally restricts the use of individual methods. Therefore, proper diagnostics requires identifying the specific component returning the error.
Too Many Requests from a Single User or IP Address
One of the most common causes is exceeding a limit set for a particular IP address or user session. Such rules are used to protect login forms, search functions, user accounts, and other features that may generate significant load.
Intensive activity is not necessarily intentional. A user may repeatedly refresh a page, click a button again after a delayed response, or open numerous tabs. A browser may also automatically perform background operations, such as checking for updates, loading additional data, or synchronising information.
A separate situation arises when several people share one public IP address. This is common in corporate networks, public Wi-Fi connections, and connections using CGNAT technology. If the server only considers the IP address, the activity of different users may be combined. As a result, a restriction may be triggered even for someone who has not personally performed an excessive number of operations.
Administrators should verify which parameter the system uses to identify clients. An IP address does not always reliably distinguish one user from another, so authenticated services may benefit from applying limits at the account or token level.
API Restrictions and Rate Limiting
Many public and commercial APIs use request rate limits to distribute resources among clients. A service provider may establish a maximum number of operations per second, minute, hour, or another period. Additional quotas may apply to daily usage, concurrent connections, or individual methods.
For example, an application synchronises product inventory, prices, and orders with an external platform. If it sends hundreds of requests simultaneously during synchronisation, the API may return 429 for some operations. The integration does not necessarily stop working completely: successful responses may alternate with rejected ones.
It is important to distinguish between rate limits and general quotas. Rate limiting typically controls request intensity over a short interval, while a quota may determine the total service usage allowed per day or month. Depending on the implementation, exceeding either type of restriction may result in HTTP 429, although the rules for restoring access will differ.
Some APIs return additional headers containing information about the established limit, the number of remaining operations, and when the limit resets. The names and formats of these headers depend on the specific service. Therefore, developers should consult the platform’s official documentation when building integrations.
If an application automatically retries a failed operation without delay, the problem may recur after each restoration of access. This behaviour creates additional load and prevents the system from returning to normal operation.
Excessive Server Load
A sudden increase in visitors or simultaneous operations can activate infrastructure protection mechanisms. This may happen during advertising campaigns, seasonal sales, the publication of popular content, or other events that generate peak traffic.
However, it is necessary to distinguish between high server load and exceeding an established limit. Running out of RAM or CPU resources does not automatically mean that the server will return 429. Under such circumstances, delays, timeouts, or 5xx errors may occur. Code 429 appears when the relevant component applies a policy restricting the request rate.
For example, a load balancer or security service may restrict requests to a resource-intensive URL to prevent the backend from becoming overloaded. If the configured thresholds are too low, even a legitimate traffic spike may result in some users being blocked.
Insufficient server resources can indirectly make the problem worse. If an application processes operations slowly, the number of concurrent connections increases, and clients may retry requests because of delays. Therefore, the situation should be assessed comprehensively by analysing CPU load, memory usage, the number of active connections, response times, and statistics on triggered limiting rules.
Bot Activity and Automated Scripts
Automated tools can generate significantly more intensive traffic than ordinary visitors. These include search engine crawlers, scrapers, monitoring systems, integration scripts, testing tools, and programs that regularly check websites for changes.
Not all automated traffic is unwanted. Search engines crawl pages for indexing, monitoring services check resource availability, and external integrations enable data exchange. Problems arise when the frequency of these requests exceeds the established limits.
For example, a scraper may open thousands of product pages consecutively without pauses, while a monitoring script may check the same URL too frequently. In server logs, such activity usually appears as a large number of similar requests, short intervals between them, or recurring URL patterns.
Automated login attempts and credential guessing require particular attention. In these scenarios, rate limiting is an important security mechanism that reduces the speed of password guessing. However, HTTP 429 alone does not prove that a cyberattack is taking place: such a conclusion requires an analysis of traffic behaviour.
Incorrect Caching or Software Configuration
Sometimes the website itself becomes the source of excessive requests. JavaScript errors, incorrectly implemented background processes, repeated AJAX operations, or poorly configured plugins can generate a continuous stream of requests even when visitor numbers are low.
For example, a software component may repeatedly call an API after each interface update. If a change in the page state triggers a new call, and the resulting response changes that state again, a loop occurs. As a result, a single user can generate dozens or hundreds of unnecessary requests within a short period.
Similar problems occur with CMS background tasks. An incorrectly configured scheduler may run identical processes in parallel, while a synchronisation module may repeatedly retry operations after a failure. For WordPress, it is worth checking WP-Cron, AJAX handlers, the REST API, and installed extensions separately.
A lack of effective caching can also increase the number of requests to the backend. If the browser or an intermediate cache does not reuse previously retrieved resources, the application must contact the server again. This does not necessarily cause 429 directly, but under certain conditions it accelerates the process of reaching established limits.
At the same time, caching must be configured selectively. Static files and public data can often be cached, while personalised responses, administrative operations, and confidential information require separate rules.
How to Find the Cause of Error 429?
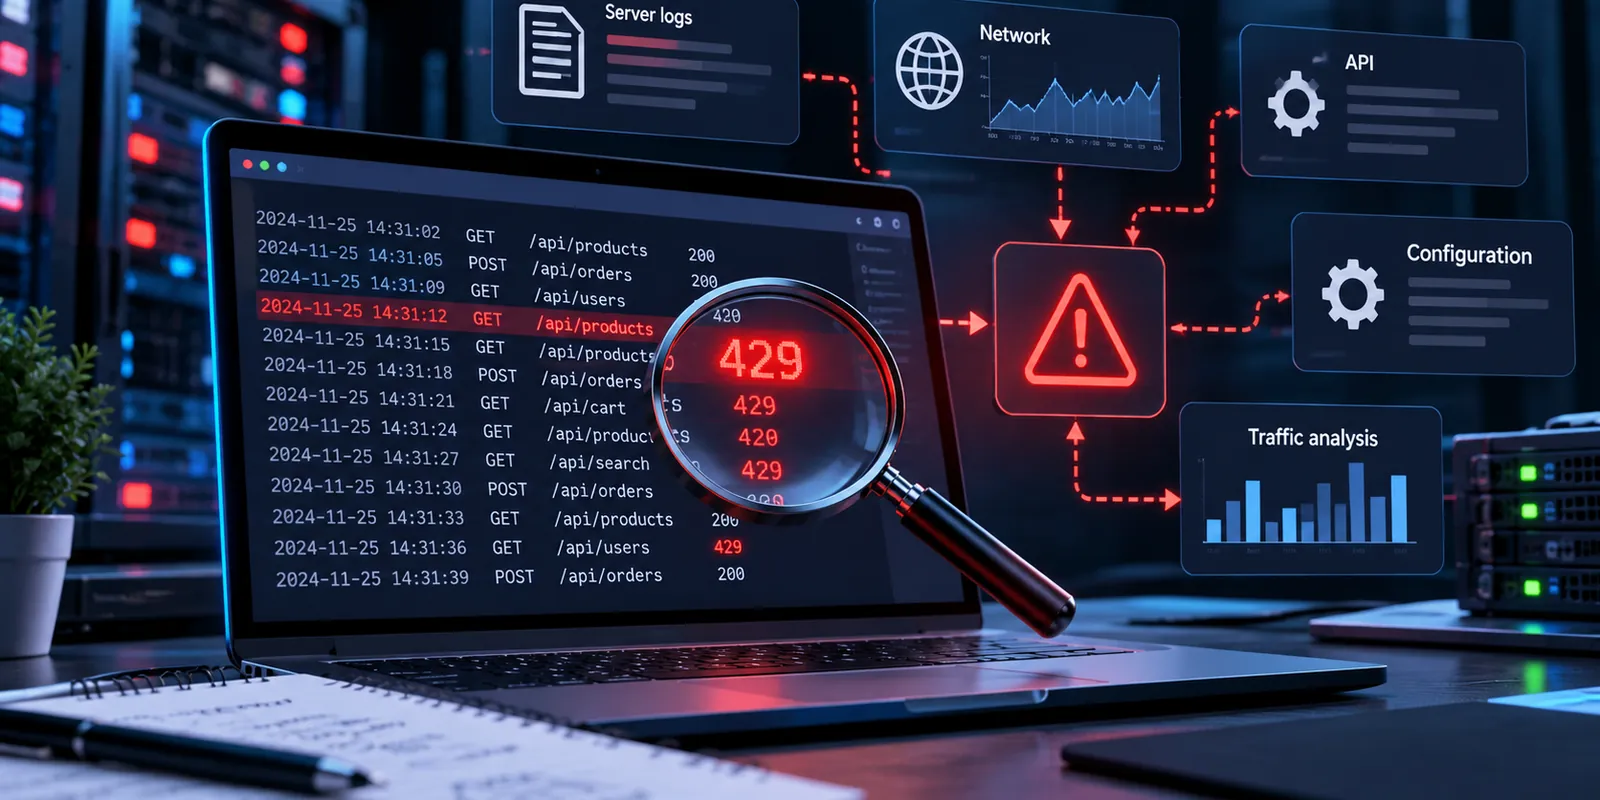
Diagnostics should begin by determining the scope of the problem. First, establish whether the error affects all users, only users from a particular network, specific operations, or users after prolonged interaction with the website. This helps determine whether the restriction applies to an IP address, account, individual URL, or the entire infrastructure.
If the problem occurs in a browser, open the developer tools, navigate to the Network tab, and locate the request with status 429. Its details allow you to examine the URL, HTTP method, response headers, execution time, and other parameters. Checking Retry-After is particularly useful if the server provides this header.
For APIs, similar information can be obtained through application logs, an HTTP client, or testing tools. It is important to record not only the error message but also when it occurred, the operation identifier, and information about the server response.
If you have access to the infrastructure, the next step is to analyse the logs of the web server, proxy, CDN, WAF, and application itself. Keep in mind that a restriction may be triggered before the request reaches the origin server. In that case, the corresponding entry may be absent from the web server logs.
For a systematic investigation, follow this sequence of steps:
- Record the circumstances of the error. Identify the exact time, URL, operation type, IP address, or client identifier. Check whether the problem occurs continuously or only during peak load.
- Examine the HTTP response. Check the status, Retry-After, and other available headers that may contain information about limits or the component that processed the request.
- Analyse the logs. Find entries for the relevant period and assess request frequency, recurring URLs, traffic sources, and response codes.
- Check the restriction settings. Examine rate limiting rules at the CDN, WAF, proxy, web server, application, and external API levels.
- Investigate automated processes. Check background tasks, plugins, scripts, integrations, monitoring systems, and bot behaviour.
- Compare the results with server load. Assess CPU and RAM usage, database activity, the number of concurrent connections, and server response times.
After completing these steps, you can narrow down the possible causes and determine whether you need to change client behaviour, optimise the application, or adjust server rules.
For Nginx diagnostics, access logs and error logs can be useful. Apache also uses access and error logs. However, the standard logging format does not always contain all the information required to identify a specific rate limiting rule. Sometimes additional logging must be configured, or diagnostic data from the security service must be examined.
It is important to identify the client’s actual IP address correctly during the investigation. If a reverse proxy or CDN operates in front of the web server, the logs may show the intermediate server’s address. Special headers and trusted proxy settings are used to retrieve the real address. Trusting an arbitrary X-Forwarded-For header supplied by a client is dangerous because its value can be forged.
Timing patterns should also be investigated. If the error appears at regular intervals, it may indicate a scheduled task or recurring script. If the problem coincides with advertising activity or a sudden increase in traffic, peak-load protection rules should be examined.
The following table will help you identify the appropriate diagnostic approach depending on the nature of the problem.
| Symptom | Possible Cause | What to Check |
|---|---|---|
| 429 occurs for only one user | A limit based on IP address, session, or account | Client identifier, operation frequency, blocking rules |
| The error appears when working with an API | Exceeded quota or rate limit | API documentation, response headers, number of calls |
| The problem occurs during peak traffic | Security rules triggered by increasing load | Traffic statistics, server resources, CDN and WAF settings |
| 429 recurs at regular intervals | A background task or automated process | Schedulers, integrations, script execution logs |
| The number of requests increased sharply after a website update | An error in the code or plugin behaviour | Recent changes, JavaScript, AJAX, REST API, background processes |
| The error appears in CDN logs but not in web server logs | The restriction is triggered at an intermediate layer | CDN and WAF rules, security logs, event identifiers |
These symptoms help formulate a hypothesis but do not replace an analysis of actual data. The same response code may result from different rules, and several limiting mechanisms may operate simultaneously.
How to Fix the 429 Too Many Requests Error?
The solution depends on who controls the source of intensive traffic and at which level the restriction is triggered. For an ordinary visitor, the solution often involves waiting and stopping repeated attempts. For an API integration developer, it involves changing the algorithm used to interact with the service. For a website administrator, it involves checking rate limiting rules, software components, and server load.
If the 429 too many requests message appears while browsing a website, first stop refreshing the page repeatedly. Frequent retries may continue to exceed the limit, particularly if the system uses a sliding time window or counts every new request.
If the server provides Retry-After, follow the specified waiting period. If this header is absent, you can wait for a while and then try again. The waiting time depends on the configuration of the specific service, so there is no universal interval.
Website owners and developers should take a more systematic approach. First, determine whether the current restrictions are justified. If they protect authentication against automated password guessing, simply increasing the permitted rate may weaken security.
Optimising request frequency. In many cases, the most effective solution is to eliminate unnecessary operations. For example, a search field does not necessarily need to contact the server after every character entered. The debounce mechanism allows a search to run after a short pause in typing, while throttle limits how frequently a function can be called.
For API integrations, it is advisable to use task queues, concurrency limits, and execution rate controls. Instead of sending numerous operations simultaneously, an application can process them in small batches while respecting established quotas.
Implementing retries correctly. If the server returns 429, the client should not continuously repeat the same operation. Automated systems use exponential backoff, an algorithm that gradually increases the delay between retry attempts. For example, after the first failed attempt, the client may wait one second, then two seconds after the next attempt, followed by four seconds. This is only an illustration of the principle, not a universal approach for all APIs.
A random component known as jitter is often added to these delays. It helps prevent situations in which a large number of clients simultaneously retry requests after identical waiting periods. If the API provides Retry-After or other recovery rules, they must be taken into account by the algorithm.
Operations must also be retried with consideration for their idempotency. For example, automatically repeating an order creation or payment operation without appropriate safeguards may result in duplicate actions. Therefore, the retry policy must consider the HTTP method, operation type, and whether the operation can be safely repeated.
Configuring caching. Caching helps reduce repeated requests to the backend and lower resource consumption. Browser caching and a CDN can be used for static files. Public API data can benefit from response caching with an appropriate validity period. Dynamic pages can use server-side caching where it is compatible with the application’s logic.
However, caching is not a universal solution. If 429 is generated at the CDN level before the request reaches the origin server, optimising server-side caching may not affect the specific restriction. Similarly, caching will not fix an infinite JavaScript loop if the browser continues sending new requests.
Adjusting server limits. After analysing actual traffic, you can change the permitted request rate, the duration of the counting window, or the rules for individual routes. For example, a public catalogue page and an admin login form do not necessarily need the same restrictions.
In Nginx, the ngx\_http\_limit\_req\_module is one of the modules used to control request rates. It allows administrators to define counting zones, processing rates, and parameters for short traffic bursts. Configuration details are described in the official Nginx documentation.
An important technical detail is that the default response code for rejected requests in this module is 503 unless the administrator configures another value. The limit\_req\_status 429 directive is used to return 429 specifically. Therefore, the presence of rate limiting does not guarantee that the server will automatically return HTTP 429.
Checking the software. If plugins, background tasks, or code errors cause the problem, unnecessary calls must be eliminated. It is advisable to check recent CMS updates, modified components, repeated AJAX operations, schedulers, and integrations with external services.
For WordPress, special attention should be paid to extensions that regularly interact with the REST API or admin-ajax.php. With high visitor numbers or incorrect settings, they may generate significant background traffic. However, these mechanisms should not automatically be considered the cause without confirmation in the logs.
Assessing infrastructure resources. If restrictions regularly trigger during normal peak traffic, check whether the current configuration meets the website’s actual requirements. Database optimisation, caching configuration, or increasing available computing resources may help reduce the load.
For projects that require control over the server environment, you can consider VDS/VPS from Hostpark or dedicated server rental in Ukraine. The choice depends on the workload, application architecture, and required resources. However, moving to another server will not eliminate 429 if the cause is a fixed external API quota, a WAF rule, or a software error.
How to Distinguish 429 from Other Server Errors?
HTTP status codes help identify the nature of a problem during communication between a client and a server. However, similar visible symptoms – a page failing to load, data not being retrieved, or a function no longer working – may be accompanied by different responses.
Error 429 belongs to the 4xx class and indicates that the permitted number of requests has been exceeded. Other codes in this class may indicate an incorrectly formatted request, denied access, or a missing resource. Codes in the 5xx class generally indicate problems on the server side or within an intermediate component.
The following table compares the most common HTTP codes that may appear when diagnosing website availability problems.
| HTTP Code | Meaning | Main Difference from 429 |
|---|---|---|
| 400 Bad Request | The server cannot or will not process the request because of an error it considers to be client-related | The problem is related to an invalid request, not necessarily its frequency |
| 403 Forbidden | The server understood the request but refuses to fulfil it | Access is denied, but the reason is not necessarily related to exceeding a limit |
| 404 Not Found | The server cannot find the requested resource or does not wish to disclose its existence | The problem concerns the availability of a particular resource at the specified address |
| 429 Too Many Requests | The client has exceeded the permitted request rate | The restriction is specifically related to the frequency or number of operations |
| 500 Internal Server Error | An unexpected condition occurred on the server, preventing it from fulfilling the request | Indicates an internal processing problem rather than an established rate limit |
| 502 Bad Gateway | A gateway or proxy received an invalid response from the server it contacted | The problem occurs during communication between server components |
| 503 Service Unavailable | The server is temporarily unable to process the request, for example because of overload or maintenance | Indicates temporary service unavailability, not necessarily that a client limit has been exceeded |
It is particularly important to distinguish between 429 and 503. Both codes may appear during intensive traffic, but they have different meanings. HTTP 429 indicates excessive client activity according to established rules. HTTP 503 indicates that the server is temporarily unable to process a request. However, a particular implementation of a protection mechanism may use 503 instead of 429.
Code 403 is also sometimes confused with 429 because both may appear after a security system is triggered. For example, a WAF may return 403 if it considers a request suspicious, or 429 if a rate threshold has been exceeded. The status selected depends on the security component’s configuration.
It is also worth noting that Retry-After can be used not only with 429 but also with other statuses, including 503. Therefore, the presence of this header alone does not determine the type of problem.
For accurate diagnostics, it is necessary to analyse the actual HTTP status, headers, logs, and infrastructure configuration. The error message displayed in the browser does not always contain enough information to identify the root cause.
How to Prevent Error 429 in the Future?
Preventing HTTP 429 involves balanced restriction settings and monitoring actual server load. The goal is not to disable rate limiting completely but to ensure that protection mechanisms do not interfere with normal user activity while still restricting excessive automated traffic.
First, identify which operations generate the greatest load. For one website, these may be search queries to the database; for another, authentication, API integrations, background tasks, or mass loading of dynamic pages.
Limiting rules should be configured according to the purpose of individual functions. For example, stricter restrictions may be justified for a login form than for browsing a public catalogue. Individual quotas can be applied to authenticated API clients, while resource-intensive operations can have additional concurrency controls.
When choosing a rate limiting algorithm, consider the characteristics of the traffic. A fixed time window is simple to implement but may allow short bursts at the boundary between two intervals. A sliding window provides more precise activity control over a specified period. Token bucket and leaky bucket algorithms are used to regulate request rates, allowing control over short bursts or smoothing the flow of operations.
There is no universally best algorithm. The choice depends on application requirements, acceptable latency, expected traffic fluctuations, and infrastructure capabilities.
For long-term stability, it is worth implementing several practical measures:
- Monitor traffic intensity. Track the number of requests, the proportion of 429 responses, activity sources, and the most heavily loaded URLs.
- Configure limits for different operations. Use separate rules for authentication, APIs, public pages, and resource-intensive functions.
- Optimise application performance. Eliminate unnecessary AJAX calls, infinite loops, duplicate background tasks, and uncontrolled retries.
- Use caching where appropriate. Reduce repeated loading of static resources and public data without compromising information accuracy or confidentiality.
- Control automated traffic. Analyse the behaviour of bots, scrapers, crawlers, and integrations without unnecessarily blocking legitimate services.
- Handle API responses correctly. Respect quotas and Retry-After, and use queues and retry algorithms with gradually increasing delays.
- Review the configuration regularly. Adjust restrictions after changes in traffic, website functionality, or infrastructure architecture.
These measures help reduce false positives and maintain predictable service operation. It is especially important to review settings regularly after introducing new features, integrations, or advertising campaigns, as traffic patterns change over time.
For APIs, it is advisable to implement a centralised mechanism for managing operation frequency. If several processes use the same access key, each should not independently consume the entire available quota. A shared queue or coordinator allows overall request intensity to be controlled and prevents competition between components.
In distributed systems, it is also important to consider where rate limiting counters are stored. If each server applies its own independent limit, system behaviour may depend on which node receives the client request. For consistent control, a centralised counter store or mechanisms supported by a load balancer or API gateway may be used.
Another important area is monitoring. It is worth tracking not only the total number of 429 responses but also the proportion of rejected operations for individual routes, clients, and time intervals. A sharp increase in this metric may indicate a change in bot behaviour, an error introduced by an update, or a mismatch between current rules and actual traffic.
For critical services, it is useful to configure automatic alerts when the number of 429 responses exceeds normal levels. Alert thresholds should preferably be based on historical data so that the system does not react to every minor fluctuation.
Testing the configuration before deployment is equally important. Load testing helps verify how an application behaves during short traffic spikes, whether HTTP statuses are returned correctly, and whether normal processing resumes after the restriction period ends. Such tests should be performed under controlled, agreed conditions, taking into account the infrastructure’s acceptable load.
Interaction with search engine crawlers also requires special attention. If a search crawler regularly receives 429, it may have difficulty crawling the resource. Unrestricted access should not be granted without verification to any client claiming to be a search engine bot, because the User-Agent can be spoofed. To verify legitimate crawlers, use the methods recommended by the relevant search engines.
For WordPress websites, prevention also includes monitoring installed plugins, regularly checking background processes, optimising database performance, and configuring caching correctly. If several extensions perform similar functions or simultaneously contact external APIs, it is worth checking whether duplicate operations can be reduced.
Ultimately, effective protection depends on balance. Restrictions that are too weak may fail to prevent unwanted activity, while those that are too strict may block real visitors and disrupt integrations. Regular traffic analysis helps maintain this balance without unjustifiably increasing limits.
Conclusion
429 Too Many Requests is an HTTP error that occurs when the established frequency or number of requests to a server or API has been exceeded. Most often, it results from a rate limiting mechanism designed to control load and protect infrastructure. Code 429 itself does not indicate a critical server malfunction, although it may point to problems with configuration, application logic, or traffic behaviour.
To fix the error, first identify the source of excessive activity, check HTTP headers, analyse logs, and determine which component is applying the restriction. You can then optimise application performance, reduce unnecessary operations, configure caching, or review rate limiting rules. Simply increasing the permitted number of requests without analysing the cause does not always solve the problem and may sometimes weaken security.
If HTTP 429 regularly occurs on a website, it is worth checking not only the software but also the server infrastructure configuration. Hostpark offers VDS/VPS and dedicated servers for hosting web projects with different resource requirements. Hostpark specialists can help select an appropriate server solution based on the project’s needs. Any additional work involving application configuration or its security mechanisms is agreed upon separately.